The bottleneck in systematic research is not ideas. It is the twelve hours of plumbing between an idea and a number I am willing to trust.
Read a paper, form a hypothesis, find the data, write the code, back it, discover the lookahead, fix the lookahead, run a walk-forward, write the memo, build the deck, watch it trade. Most of that work is mechanical, and most of the mistakes are mechanical too — an off-by-one in a shift, a survivorship bias in a universe, a parameter chosen after seeing the answer.
Large language models finally made the mechanical part cheap. They did not make it trustworthy. A model asked to improve a Sharpe ratio will improve the Sharpe ratio, on paper, whether or not the improvement exists. So the design constraint for ForgeAlpha is simple and absolute: agents may propose anything, but they never get to run the scoreboard. Every performance number in the system comes out of deterministic software.
A reference architecture, complete enough to diagram, estimate and build against — not a claim of live results. Stack choices are one coherent implementation among several. Where I show numbers, they come from my own strategy library running through the same gates, not from ForgeAlpha itself.
01Why this exists
I built the first version of this loop by hand. My research library — eight strategies, twenty-six years of data, walk-forward on every one — is what the hand-built version produces: notebooks, a vectorbt stack, a rebuild script, five write-ups, four company reports. It works, and it is the reason I know exactly which parts deserve to be automated and which parts must stay boring.
Three things convinced me to design the whole thing as a platform rather than a script collection.
First, throughput is a systems problem. One analyst can hold maybe three live questions at once. The constraint is not intelligence; it is the serial cost of context-switching between data, code, results and prose. Fan-out fixes that, but only if the parallel branches cannot corrupt each other.
Second, the failure modes compound. A lookahead bug in one notebook is a mistake. A lookahead bug in the shared library is a systematic bias in every result the firm produces, forever. Once research is generated faster than a human can audit it, the audit has to be code.
Third, most ideas should die early and cheaply. The most valuable component in the system is not the model that generates a strategy. It is the counter that stops the fourth variation of a dead idea.
02What it does
ForgeAlpha takes one of two inputs and runs one pipeline.
An idea. A sentence, a paper, a chart, a complaint about a market. The research agent turns it into a testable hypothesis with data requirements and prior art. A return stream. A series I can see but cannot explain — a manager's track record, a public strategy, a sleeve in a portfolio — which the reverse-engineering engine tries to reproduce from a library of candidate rules.
Both paths converge on the same output: versioned strategy code, an in-sample backtest, a walk-forward validation report, an institutional write-up with a branded deck, and a paper-trading harness that keeps watching after I stop.
03The research loop
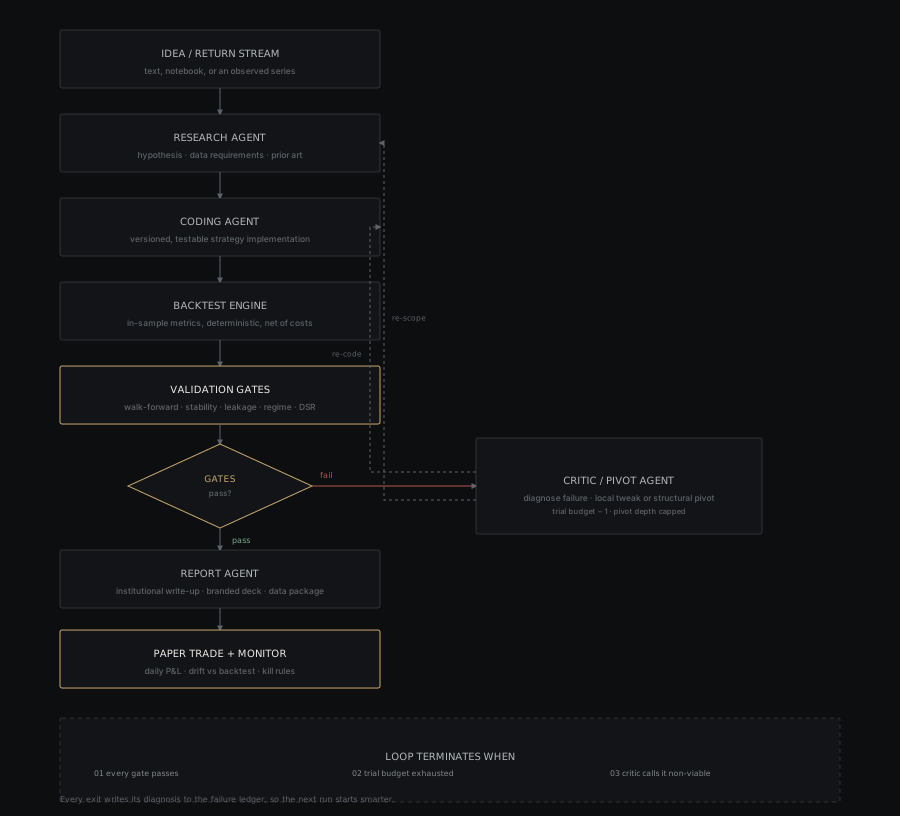
Six roles in sequence, one branch back, two hard stops.
The research agent produces a hypothesis, the data it needs and what the literature already says. The coding agent writes the strategy against a fixed interface, with tests. The backtest engine returns in-sample metrics net of costs. The validation agent runs the gates. If the gates fail, the critic diagnoses — not "try another parameter" but which assumption broke — and sends the work back to coding for a local fix or to research for a structural pivot.
The loop terminates on exactly three conditions: every gate passes, the trial budget is exhausted, or the critic declares the thesis non-viable. There is no fourth condition where the system keeps going because it has budget left in the month.
04Architecture
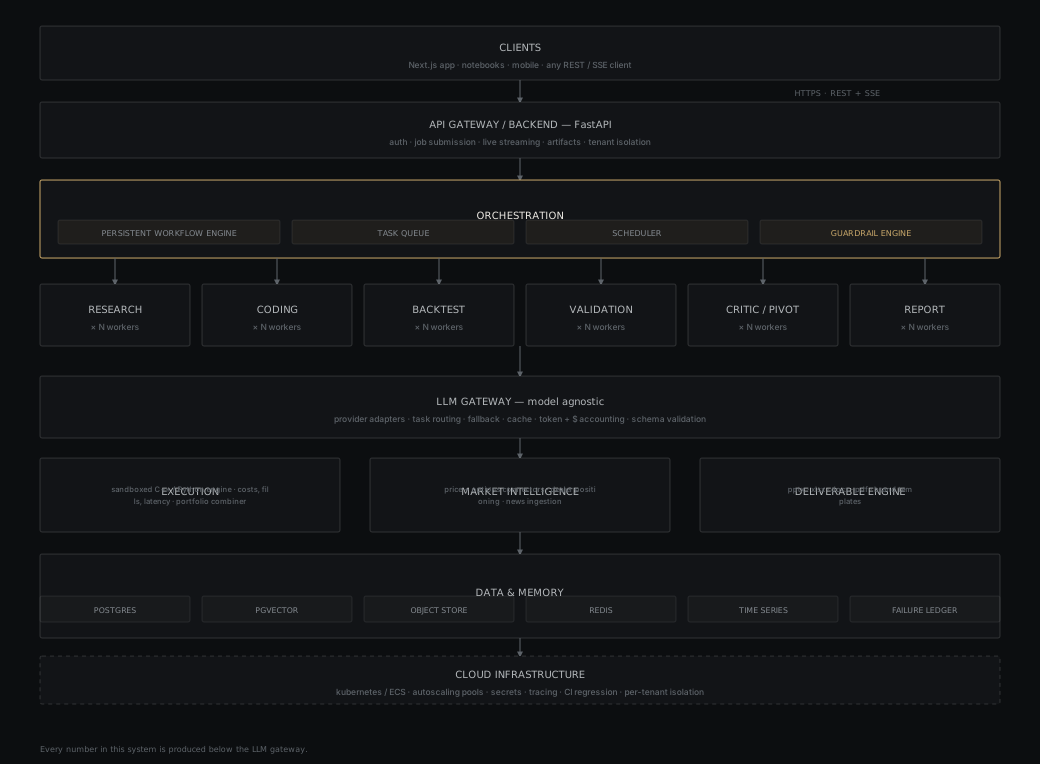
Four seams, deliberately cut in the same places every time.
The API is the product. A FastAPI backend owns every business rule. The Next.js app is a client like any other; so is a notebook, a phone, or a cron job. Submission returns a job ID immediately, and clients subscribe to server-sent events for agent activity, intermediate metrics and artifacts.
The orchestrator owns state. Each idea is a durable workflow instance — a persistent state machine that survives a process restart and can be resumed mid-flight. Agents are stateless workers pulling from a queue. They share nothing except the database and the queue, which is why adding capacity is just adding workers.
The gateway owns model choice. One internal interface for generation, tool calls and embeddings, with provider adapters behind it. Swapping models, mixing providers per task, or failing over mid-run is a configuration change, not a refactor.
The execution plane owns truth. The backtest engine, the market data, and the deliverable engine sit below the LLM gateway, where no model output can reach a performance number.
05The agents
Each role owns one kind of artifact, and the boundaries are enforced by tools rather than by prompt discipline. The coding agent cannot see the validation report; the validation agent cannot see the code's intent, only its behaviour. That separation is what stops the system from grading its own homework.
| Agent | Owns | Tools |
|---|---|---|
| Research | Hypothesis, data requirements, prior art | Knowledge base, web ingestion, data catalog |
| Coding | Versioned strategy implementation | Sandboxed Python, linter, unit tests |
| Backtest | Historical simulation | C++/Python engine |
| Validation | Walk-forward, stability, leakage, regime | WFA engine, statistical library |
| Critic / Pivot | Diagnosis, local fix or structural pivot | Failure ledger, strategy registry |
| Report | Narrative and branded deliverables | Deliverable engine, charting |
| Monitor | Paper and live performance tracking | Paper broker, alerting |
| Reverse-engineering | Inferring the model behind a series | Feature library, search |
| Intelligence | Signal and headline synthesis | Market connectors, news pipeline |
Fan-out is the default: one idea spawns branches, each branch is an independent workflow with its own budget, and a portfolio-level pass ranks the survivors and looks for blends that are more robust than any single component. The combination engine has its own out-of-sample check, because a blend is another model and deserves the same suspicion.
06Software judges, models propose
Task routing is the cheap version of model selection. Planning, critique and writing get the strongest model available; coding gets a mid-tier model with good tool use; extraction, classification and summarisation get the fastest thing that clears a schema.
| Task type | Model tier | Why |
|---|---|---|
| Planning, critique, structural pivots | Frontier | Judgment about what to try next is where capability actually pays |
| Strategy code, refactors, tests | Mid | Bounded by the interface and the test suite, not by the prose |
| Extraction, tagging, summaries | Small / fast | Volume work where a schema check catches nearly every error |
| Embeddings | Dedicated | Stable vectors matter more than a fashionable model |
Underneath the routing: automatic fallback, exponential backoff, response caching, structured-output validation against a schema, and per-workflow token and dollar accounting against a budget. The gateway is also the only place that knows a provider exists, which is what makes the "model-agnostic" claim architectural rather than aspirational.
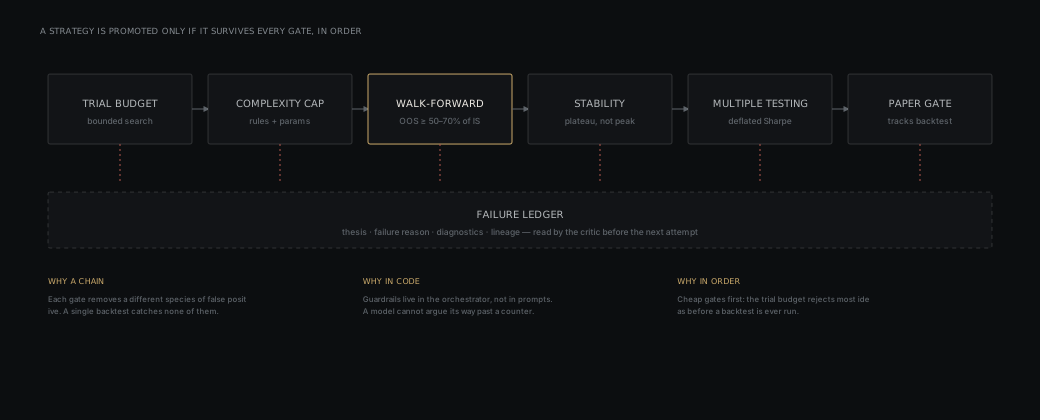
The rule I keep coming back to: a prompt is not a guardrail. If a constraint matters, it lives in the orchestrator as a counter, a schema or a gate. Anything that exists only as an instruction in a system prompt is a suggestion, and I have watched suggestions get negotiated away by a model that was being helpful.
07The backtest engine
Python for the interface, C++ for the loop, and a hard boundary between them.
The core is an event-driven engine with configurable bar handling: costs, slippage, latency, partial fills and rebalance timing are explicit parameters rather than assumptions baked into a vectorised shortcut. Python bindings expose a small API — load data, set weights, run, read metrics — so an agent can drive it without ever touching the internals.
Runs execute in isolated containers with no outbound network except approved data endpoints, CPU and memory limits, reproducible seeds, and a configuration snapshot stored with the result. Two identical runs produce identical numbers, or the run is a bug.
Because engine changes can silently rewrite history, the engine has a regression suite pinned to reference results: a set of strategies with known outputs that must reproduce to the basis point before any release. This is the same instinct that made me write the research library as a rebuildable pipeline rather than a pile of notebooks.
08Validation gates
Six gates, cheapest first, each removing a different species of false positive.
| Gate | Removes | Reference setting |
|---|---|---|
| Trial budget | Search that continues until something works | Fixed configurations per idea, decremented in code |
| Complexity cap | Rules fitted to noise | Hard limit on parameters and rule count |
| Walk-forward | In-sample-only edges | Rolling 5y in / 1y out, stepped 6–12 months |
| Stability | Single-cell peaks | Performance must hold across a parameter neighbourhood |
| Multiple testing | Luck dressed as skill | Deflated Sharpe using the trial count |
| Paper gate | Backtest-only behaviour | Live results must track the backtest distribution |
Here is the same gate applied to my own library: eight strategies, eleven rolling folds each, parameters re-selected inside every training window. Eighty-eight out-of-sample folds, mean in-sample Sharpe 0.79, mean out-of-sample 0.70, ninety per cent of folds profitable after costs.
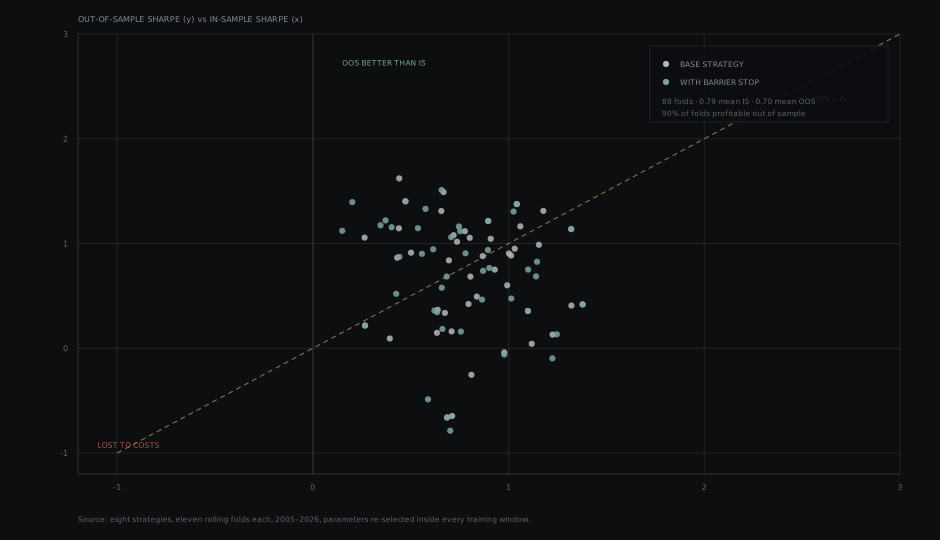
What I care about in that chart is not the average. It is the shape of the tail: the folds where out-of-sample collapsed to half of in-sample are the ones that would have taken capital if the gate were a person in a hurry.
09Overfitting as an architecture problem
Everybody agrees overfitting is bad. Almost nobody prices it. The reason is that overfitting is not a moral failing, it is a search process that succeeds at the wrong objective — and the fix is not discipline, it is a budget.
Trial budgets. Each idea gets a fixed number of configurations. Five, not five hundred. The budget is a counter in the orchestrator; the agent is told how many it has left, and when it hits zero the workflow ends whether or not the last run looked promising.
Deflated Sharpe. Every reported Sharpe is adjusted for how many things were tried before it. When a run reports 1.4 after nine attempts, the number the system ranks on is the deflated one. This is the same adjustment I applied by hand in the strategy library, where nine grid cells per family deflated the best Sharpe from 0.996 to 0.969.
Pivot depth. The critic may pivot structurally at most twice. A third pivot means the idea has become a different idea, and it enters the queue as a new hypothesis with a new budget rather than quietly inheriting the old one's sunk cost.
Complexity ceilings. A hard cap on parameters and rules. If a strategy needs eleven free parameters to fit twenty-six years, it is describing the sample.
10Memory that compounds
The most valuable table in the database is the failure ledger. Every dead idea keeps its thesis, its failure reason, the diagnostics, and its lineage — and the critic reads the ledger before proposing anything. A system that forgets why it failed will rediscover the same failure at full price, weekly.
Three kinds of memory, retrieved into context at the start of every run:
- Episodic — what was tried, decided and observed in previous runs.
- Semantic — durable facts: mandate constraints, preferences, validated findings.
- Lineage — parent and child relationships between strategies, with full result history, so a "new" idea that is a renamed version of a retired one is caught immediately.
Memory is also where the honest cost shows up. Retrieval is a latency and token tax on every run, and bad memory is worse than none: a stale lesson retrieved with confidence will send the critic down a path that was already closed. Every memory entry carries its provenance and the date it was validated.
11The knowledge base
Books, papers, filings and public research go in through an ingestion pipeline: parse, OCR where needed, chunk, embed, tag. Storage is pgvector with hybrid search — embeddings plus keyword — followed by a reranking pass, and every retrieved passage carries a citation back to the source page.
Retrieval carries the factual load. Fine-tuning, where a provider permits it, is reserved for style and house conventions: how a write-up should read, how a table should be labelled. I do not want a model's weights memorising a fact that will be wrong next quarter.
12Reverse-engineering a return stream
This is the component I would use first, and the one I trust least.
Given an observed series, the engine maintains a library of candidate features — trend, mean reversion, volatility, carry, seasonality, options-derived factors, calendar effects — and agents propose rule structures that would produce that return profile. Each candidate is scored on correlation, tracking error and trade-level overlap with the observed series, then refined. The output is a best-fit rule set with a confidence score and an out-of-sample match quality, so a lucky in-sample fit is not mistaken for the answer.
The honest framing: reverse-engineering produces a hypothesis about what a manager is doing, not proof. Two different rule sets can produce nearly identical returns for years and diverge completely in the next regime. The output is useful as a question to ask, and dangerous as a conclusion to hold.
13Options and dealer intelligence
Vendor-agnostic connectors normalise equities, futures, options and commodities into one schema. On top of the options data, dealer-positioning estimates — gamma and delta exposure by strike, key levels, the strike distribution that pins price — are derived from open interest and contract greeks.
This is where index products get interesting. A gamma map tells you where hedging flows are likely to dampen or amplify moves, and that is a testable claim, not a chart to admire. Signals generated here go through the same six gates as any other idea; the options data changes the input, never the standard of evidence.
Headline and price synthesis produces short directional views with explicit confidence. Every view is logged at publication, then scored against what actually happened. A view that is not scored is a vibe.
14Deliverables that cannot invent a number
The report agent writes the narrative. The deliverable engine injects every chart, table and metric directly from the strategy registry into branded PowerPoint, Excel, Word and PDF templates.
The split matters. A model writing prose around numbers it was given is useful. A model recalling a number is a liability with good grammar. In ForgeAlpha there is no code path from model memory to a number in a document — the template placeholders are filled by the registry, and the registry is filled by the backtest engine.
What used to be an afternoon of formatting becomes seconds, which is the least interesting benefit. The interesting one is that the deck and the database can never disagree.
15Paper trading and kill rules
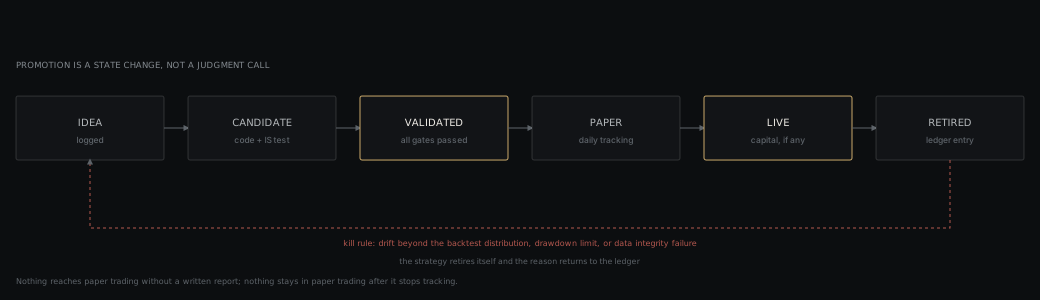
A validated strategy is promoted to paper trading through a broker paper API or an internal simulated-fill engine. A daily job updates positions, P&L and risk metrics, and compares live behaviour against the backtest distribution — hit rate, average win and loss, turnover, drawdown path.
Drift beyond a stated band, a breach of the drawdown limit, or a data-integrity failure triggers a kill rule. The strategy retires itself and the reason goes into the ledger. No committee, no waiting for the next review, no opportunity to rationalise a broken strategy into a "temporary" drawdown.
This is the part of the design I would defend hardest. A backtest is a promise about a distribution; paper trading is the first evidence about whether the promise was real. The gap between them is where most of the money is lost, and it is the gap most research infrastructure ignores entirely.
16Infrastructure
| Concern | Reference implementation | Why this way |
|---|---|---|
| Compute | Kubernetes or ECS; separate pools for workers, backtests and optional GPU | Backtests are CPU-bound and bursty; agents are not |
| State | Postgres for registry, runs, metrics, lineage | One source of truth beats five fast ones |
| Vectors | pgvector, hybrid search | Knowledge and memory live beside the data they describe |
| Artifacts | S3-compatible object storage | Decks and snapshots are immutable once written |
| Coordination | Redis for queue, cache, locks | Cheap, boring, understood |
| Isolation | gVisor or Firecracker sandboxes, no egress | Model-written code executes here |
| Observability | Structured logs, traces across agent hops, per-workflow cost | Cost per idea is a research metric |
| CI/CD | Engine regression suite against reference results | History must not change by accident |
17What I would prove
An architecture document is a set of claims waiting to be measured. These are the numbers I would want before believing any of it — and, deliberately, the ones a demo would never show.
| Claim | How it gets measured | State |
|---|---|---|
| Throughput | Ideas submitted versus strategies that pass every gate | Unmeasured |
| Survives contact | Paper-trade performance tracked against the backtest distribution | Unmeasured |
| Cycle time | Human baseline hours versus system runtime, same idea | Partly measured by hand |
| Statistical honesty | OOS Sharpe, drawdown, share of positive folds, deflated Sharpe | Measured in the strategy library |
| Signal quality | Directional views scored against subsequent price moves | Unmeasured |
| Autonomy | Share of the pipeline that ran without a human in the loop | Design target |
I would rather publish this table with two rows filled in than a demo with none of them.
18Principles
- 01Software judges, models proposeEvery performance number is produced by deterministic code. The models write, diagnose and explain; they do not score.
- 02Overfitting is a systems problemTrial budgets, complexity caps, walk-forward gates and multiple-testing adjustments belong in code, not in a style guide.
- 03The API is the productAny client drives the whole system. No business logic hides in a front end.
- 04Model-agnostic by constructionOne gateway, many providers. Yesterday's best model should be a config change, not a rewrite.
- 05Memory compoundsFailures, lineage and lessons persist and shape the next run. Forgetting is expensive.
- 06Scale by adding workersAgents are stateless and fan out. The only real limits are budget, data rate limits and model capacity.
“An autonomous research system is only as good as the gates it cannot argue with.”
Design note · ForgeAlpha, 2026Reference design. ForgeAlpha is a prototype architecture and this page documents it; nothing here is a claim of live or expected performance. Figures 1–4 are design diagrams; Figure 5 is computed from my published strategy library.
Back to work